
SK hynix and Intel Propose Shared Memory Pool as Internal Test Cuts Time to First Token From 80.76 Seconds to 15.45 Seconds, About 81 Percent, Presented in Seoul on November 12
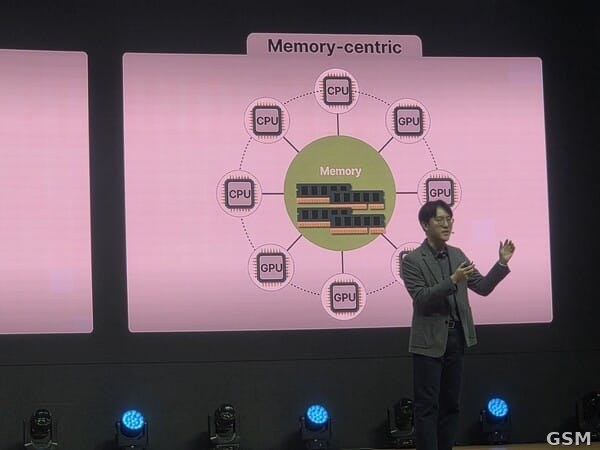
In Gangnam District, Seoul, South Korea, SK hynix presented a shared memory pool architecture on November 12 at the Intel AI Summit in Seoul. The design places high-capacity memory in dedicated racks that multiple GPU and CPU servers can access together, instead of relying only on memory attached to each individual machine. SK hynix Vice President Joo Young-pyo introduced the proposal at the summit.
The architecture targets the key-value cache that SI models build up during multi-turn conversations and tasks. The KV cache is the working memory a model keeps as generation proceeds, and the longer the context, the more memory it occupies. SK hynix said the conventional approach, in which high-bandwidth memory is attached directly to individual GPUs, leaves inefficiencies in utilization.
For connections, racks are linked by remote direct memory access, or RDMA, while connections within a rack use Compute Express Link, or CXL. The memory pool is envisioned at tens to hundreds of terabytes, installed alongside GPU racks and CPU racks. Local memory attached to existing servers stays in place, with the shared pool added on top.
SK hynix released internal test figures from an evaluation conducted with partners. In the multi-turn SI inference test, average time to first token was 80.76 seconds when eviction and recompute were used, 33.56 seconds when the cache was stored on an external solid-state drive, and 15.45 seconds when remote CXL DRAM from the shared pool was used. That is a reduction of about 81 percent from the recompute method, or roughly 5.2 times faster.
SK hynix said it will validate the architecture with Intel, customers and other strategic partners starting from the system-design phase. The materials also noted that the connection specifications between the memory pool and servers, along with the supporting software ecosystem, still need to be developed together, and that the latency and reliability of CXL-based shared memory at data center scale remain to be validated.
Source: SK hynix
Published by GSM · USA (original Chinese edition)
Photo: 图:SK海力士在英特尔人工智能峰会首尔站介绍共享内存池架构。来源:SK海力士官方发布。 / Photo: SK hynix presenting its shared memory pool architecture at the Intel AI Summit in Seoul. Credit: SK hynix.
 Silicon Carbide Nanomaterials in Disc Brake Pads: 0.5% Loading Raised Average Brake Force by Up to 19%, With Fade Resistance Up to 130°C2026-11-14
 PEBA-PEMA Blend Membrane Separates 1-Butanol With Flux of 0.19 kg/m2/h and Separation Factor of 15.5 at 5 Percent PEMA, Published in Scientific Reports on November 132026-11-14