OpenAI Releases Wet-Lab Benchmark BioBasicsBench; GPT-6 Astra Scores 66.7%
Can AI read real laboratory evidence? OpenAI, working with enzyme-design company Ligo, has introduced BioBasicsBench, a benchmark of 100 tasks that tests whether AI agents can interpret raw wet-lab evidence: gel images, colony plates, microscopy, sequencing reads and instrument exports.
At the highest reasoning setting, GPT-6 Astra earned 66.7% of the available rubric credit, against 43.8% for GPT-5.6 Sol, across 18,500 graded attempts. OpenAI says the benchmark is meant to test whether AI can handle messy experimental data in real research settings, not just answer in a demo.
The release also carries limits: the scores are OpenAI's own; 66.7% is partial rubric credit, not a pass rate; no human baseline was published, all seven models tested were OpenAI's own and no other company's models were tested, and the dataset and rubrics were not publicly linked at launch.
Source: OpenAI
Published by GSM · USA (original Chinese edition)
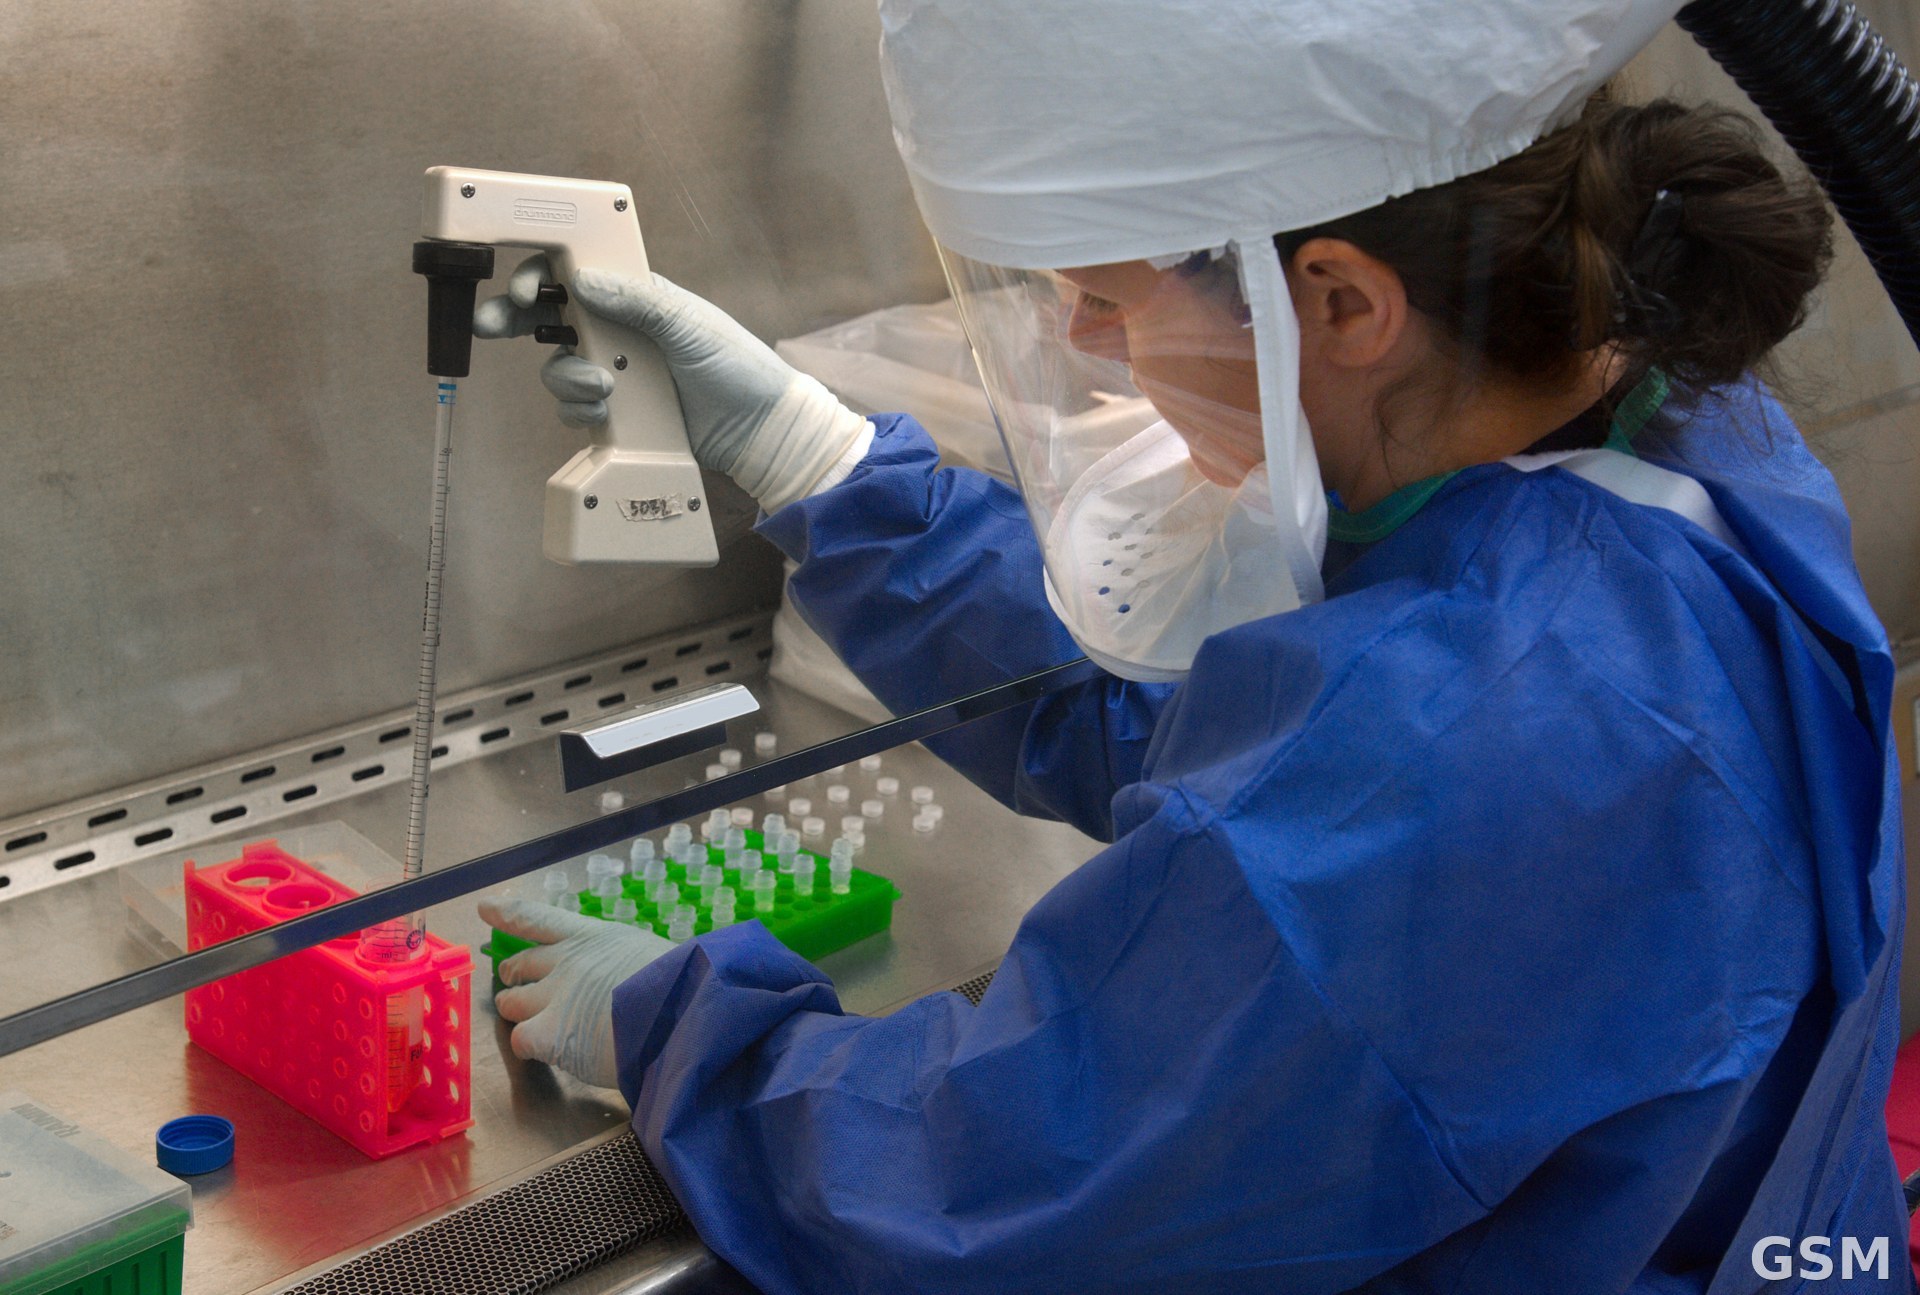
Photo: 图:实验室研究人员进行样本操作(美国疾控中心图片,公共领域)。A researcher at work in a laboratory. (CDC, public domain)